Showing posts with label web. Show all posts

Thursday, September 19, 2013

4.7: An Extended Example: Web Spiders - Part 4

The Spider is the crawler. It constructs the iterator chain we use to parse the web pages and starts the Fetcher process. Its interface to the world is an i.Forward iterator that streams out urls and some information about those urls. It operates by sending the url to the Fetcher by putting it on the Fetcher queue. It waits then for the Fetcher to return the first page. The Spider then returns the result to the caller and hands the page over to the parsing routine that runs concurrently. The parser runs through the page, queueing any urls that come out of the iterator chain. The user only blocks if there are no pages waiting on the channel from the Fetcher.

type Entry struct {
    Url, Referer string
    StatusCode   int
}

type Spider struct {
    starturl string
    entries  list.List
    queued   map[string]bool
    err      error
    fetcher  *Fetcher
    robot    Robot
    pages    chan *page
}

The Entry struct is what we return to the user. It contains the url, the page that refered it, and the status code that resulted from attempting to fetch it.
The Spider struct contains the state of the operatation: starturl is the starting url, entries contains the data we send to the user, queued we use as a log of urls we've already worked on, fetcher and robot are the two main components of teh system, and pages is the channel we use to send pages to the parsing funciton.

func NewSpider(url string) *Spider {
    url = strings.ToLower(url)
    var s Spider
    s.starturl = url
    s.robot, _ = NewRobot(url)
    s.queued = make(map[string]bool)
    s.queued[url] = true
    s.fetcher = NewFetcher()
    s.fetcher.Queue(url, url)
    s.fetcher.Run()
    s.pages = make(chan *page)
    s.parse()
    p := <-s.fetcher.Pages()
    s.err = s.processEntry(p)
    return &s
}

The constructor creates the initial state of the spider and queues and fetches the starting url. It then waits for the first page and sends it to the parser before returning.

func (s *Spider) Value() interface{} {
    return s.entries.Front().Value
}

func (s *Spider) Error() error {
    return s.err
}
func (s *Spider) AtEnd() bool {
    return s.entries.Len() == 0
}
func (s *Spider) Close() {
    close(s.pages)
    s.fetcher.Close()
}

The value we return to the user is the head of the entries queue. Once its empty, we are done. To clean up resources, the user has to call Close() on the spider, it closes the channel to the parser and shuts down the fetcher.

func (s *Spider) Next() error {
    s.entries.Remove(s.entries.Front())
    if s.AtEnd() {
        for {
            if p, ok := <-s.fetcher.Pages(); ok {
                s.err = s.processEntry(p)
                if !s.AtEnd() {
                    break
                }
            }
        }
    }
    return s.err
}

The Next() function pops the head from the queue. If it is empty it fetches the next page from the channel from the Fetcher and processes it.

func (s *Spider) processEntry(p *page) error {
    if p.err != nil {
        return p.err
    }
    s.entries.PushBack(&Entry{Url: p.url, Referer: p.ref, StatusCode: p.response.StatusCode})
    s.pages <- p
    return nil
}

The processing routine simply creates an Entry to return to the user and then sends the page off to the parsing function.

func (s *Spider) parse() {
    go func() {
        for p := range s.pages {
            if p.response.Body != nil {
                itr :=
                    HostMapper(p.url,
                        NormalizeItr(
                            UrlItr(
                                LinkItr(
                                    NodeItr(p.response.Body, DepthFirst)))))
                if s.robot != nil {
                    itr = RobotItr(s.robot, itr)
                }
                itr = BindByRef(s.starturl, Referer(p.url, itr))
                for ; !itr.AtEnd(); itr.Next() {
                    urlpair, _ := itr.Value().([]string)
                    url := urlpair[0]
                    if _, ok := s.queued[url]; !ok {
                        s.queued[url] = true
                        s.fetcher.Queue(url, urlpair[1])
                    }
                }
                p.response.Body.Close()
            }
        }
    }()
}

The parsing function loops on the channel of pages, blocking until a new one is available. When it comes through it starts a chain of iterators to filter the links on the page. Every link that comes through the chain is queued to be processed by the Fetcher.


The iterator channel built in the parsing routine is made of eight components that transform the html nodes to a pair of strings representing the url and its referer. Those processes are for the most part specialitations of i.Map and i.Filter.
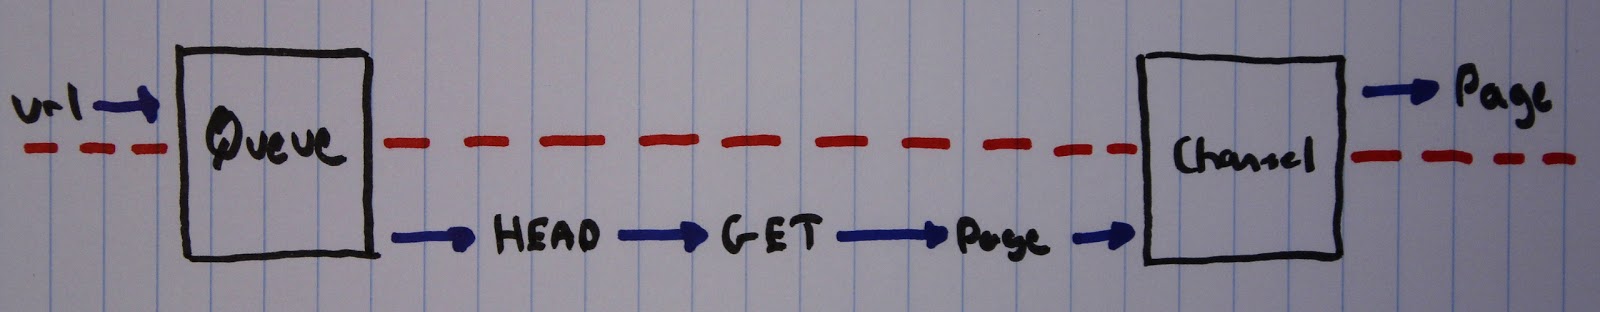
The complete process of the spider looks like this:

The two red sections represent two independent threads of execution, the Fetcher and the parse() method.
Using the spider is a simple matter of iterating through the urls that the spider returns. In this case, we want to further filter them by only printin the urls that return a error code. This is accomplished by using a hoi.FilterFunc function that checks for the StatusCode. Now we have an url checker that checks the sites for urls that are not available.

func find4xx(itr i.Iterator) bool {
    e, _ := itr.Value().(*spider.Entry)
    return e.StatusCode >= 400 && e.StatusCode < 500
}

func main() {
    s := spider.NewSpider(os.Args[1])
    itr := hoi.Filter(find4xx, s)
    count := 0
    for ; !itr.AtEnd(); itr.Next() {
        e, _ := itr.Value().(*spider.Entry)
        count++
        fmt.Printf("%d: Url: %s, Code: %d, Referer: %s\n", count, e.Url, e.StatusCode, e.Referer)
    }
    if itr.Error() != nil {
        fmt.Println(itr.Error())
    }
    s.Close()
}

Both of these source files are on GitHub at hog/spider/spider and hog/checkurls.

Wednesday, September 18, 2013

4.7: An Extended Example: Web Spiders - Part 3

The robots package is very simple since github.com/temoto/robotstxt-go does the heavy lifting of parsing and querying the robot.txt file.

type Robot interface{}

func NewRobot(url string) (Robot, error) {
    src := hostFromBase(url) + "/robots.txt"
    resp, err := http.Get(src)
    if err != nil {
        return nil, err
    }
    defer resp.Body.Close()
    robots, err := robot.FromResponse(resp)
    if err != nil {
        return nil, err
    }
    return robots.FindGroup("GoGoSpider"), nil
}
func RobotItr(rules Robot, itr i.Forward) i.Forward {
    rrules, _ := rules.(*robot.Group)
    filter := func(itr i.Iterator) bool {
        url, _ := itr.Value().(string)
        return rrules.Test(url)
    }
    return hoi.Filter(filter, itr)
}

The NewRobot() constructor uses the host name of our root url to fetch the robots.txt file and returns the rules for the GoGoSpider group (thats us!). The iterator ueses these rules to filter the url stream, rejecting any urls that are not allowed according to the rules in the robots.txt file.
The Fetcher object is the first, and only object in this system that has nothing at all to do with iterators. It doesn't consume them, doesn't produce them. What it does do is fetch and produce web pages concurrently.

type urlpair struct {
    url, ref string
}

type page struct {
    url, ref string
    err      error
    response *http.Response
}
type Fetcher struct {
    pages  chan *page
    done   chan bool
    queue  list.List
    lockq  sync.Mutex
    client http.Client
}

The urlpair is used to transport an url and its referer from the user of the Fetcher to the engine that fetches the pages. The page contains those url pairs along with the http response recieved. The Fetcher maintains page channel, a queue and a mutex to guard access to the queue.

func NewFetcher() *Fetcher {
    f := Fetcher{}
    f.pages = make(chan *page, 5)
    f.done = make(chan bool)
    return &f
}

func (f *Fetcher) Stop() {
    f.done <- true
    <-f.done
}

The constructor creates buffered channels to use in the fetching operations. It can fetch 5 pages before it blocks and has to wait.

func (f *Fetcher) Pages() <-chan *page {
    return f.pages
}
func (f *Fetcher) Queue(url, ref string) {
    f.lockq.Lock()
    defer f.lockq.Unlock()
    f.queue.PushBack(&urlpair{url: url, ref: ref})
}

The Queue() method is where links enter the fetching system. They get stored on a queue so the caller won't block (for long, only if the mutex is locked). The Pages() method gives the user access to the page channel to retrieve them. Its where the results of the queueing operation come back out to the user.

func (f *Fetcher) Run() {
    go func() {
        for {
            f.lockq.Lock()
            if f.queue.Len() > 0 {
                e := f.queue.Front()
                urlpair, _ := e.Value.(*urlpair)
                f.queue.Remove(e)
                f.lockq.Unlock()
                headResp, err := f.client.Head(urlpair.url)
                var p *page
                if err == nil {
                    content := headResp.Header.Get("Content-Type")
                    if !strings.HasPrefix(content, "text/html") || !strings.HasPrefix(content, "text/xhtml") {
                        headResp.Body.Close()
                        getResp, err := f.client.Get(urlpair.url)
                        if err == nil {
                            p = &page{url: urlpair.url, response: getResp, ref: urlpair.ref}
                        } else {
                            p = &page{url: urlpair.url, ref: urlpair.ref, err: err}
                        }
                    } else {
                        p = &page{url: urlpair.url, ref: urlpair.ref, response: headResp}
                    }
                } else {
                    p = &page{url: urlpair.url, ref: urlpair.ref, err: err}
                }
                select {
                case f.pages <- p:
                case <-f.done:
                    p.response.Body.Close()
                    for {
                        select {
                        case sentpage := <-f.pages:
                            sentpage.response.Body.Close()
                        default:
                            close(f.pages)
                            close(f.done)
                            return
                        }
                    }
                }
            } else {
                f.lockq.Unlock()
                time.Sleep(1)
            }
        }
    }()
}

The Run() method is the engine of the Fetcher. It starts a Go routine that fetches links of the queue. It performes a HEAD request on the link, checking the response and the content type of the response. If the content is an html document it performes a GET request, fetching the document. The response of the request that succeded (or the fact that it failed) is then packaged with the url and the referer variables and sent over the pages channel.
If the done channel is sending a value, the fetcher retrieves any documents from the pages channel to close them and free any resources. Once that is done, it quites the Go routine.


The red line represents the boundaries between the two threads of execution. The queue and the channel cross those boundaries.
Both of these source files are on GitHub at hog/spider/robots and hog/spider/fetcher.